Kafila: Serving Large Language Models on a Trusted Set of Heterogeneous Commodity Machines
A circle of friends or a research group owns several computers, none big enough alone to run a capable model. Kafila joins only the machines a group trusts into one ring and divides the model between them by what each can actually serve.
MEASURED RESULTS
- 4.2×
- shorter slowest stage than dividing the model uniformly, on unequal machines in three countries
- 2.6 to 3.5×
- shorter slowest stage than dividing in proportion to memory
- 1.6×
- the throughput for one user when members share a site
- 2.7×
- the aggregate throughput for four users when members share a site
Kafila also serves models for which uniform division admits no assignment at all. What the gain is worth to a user depends on how much of a token is computation rather than network: across continents most of it is network.
THE PROTOCOL
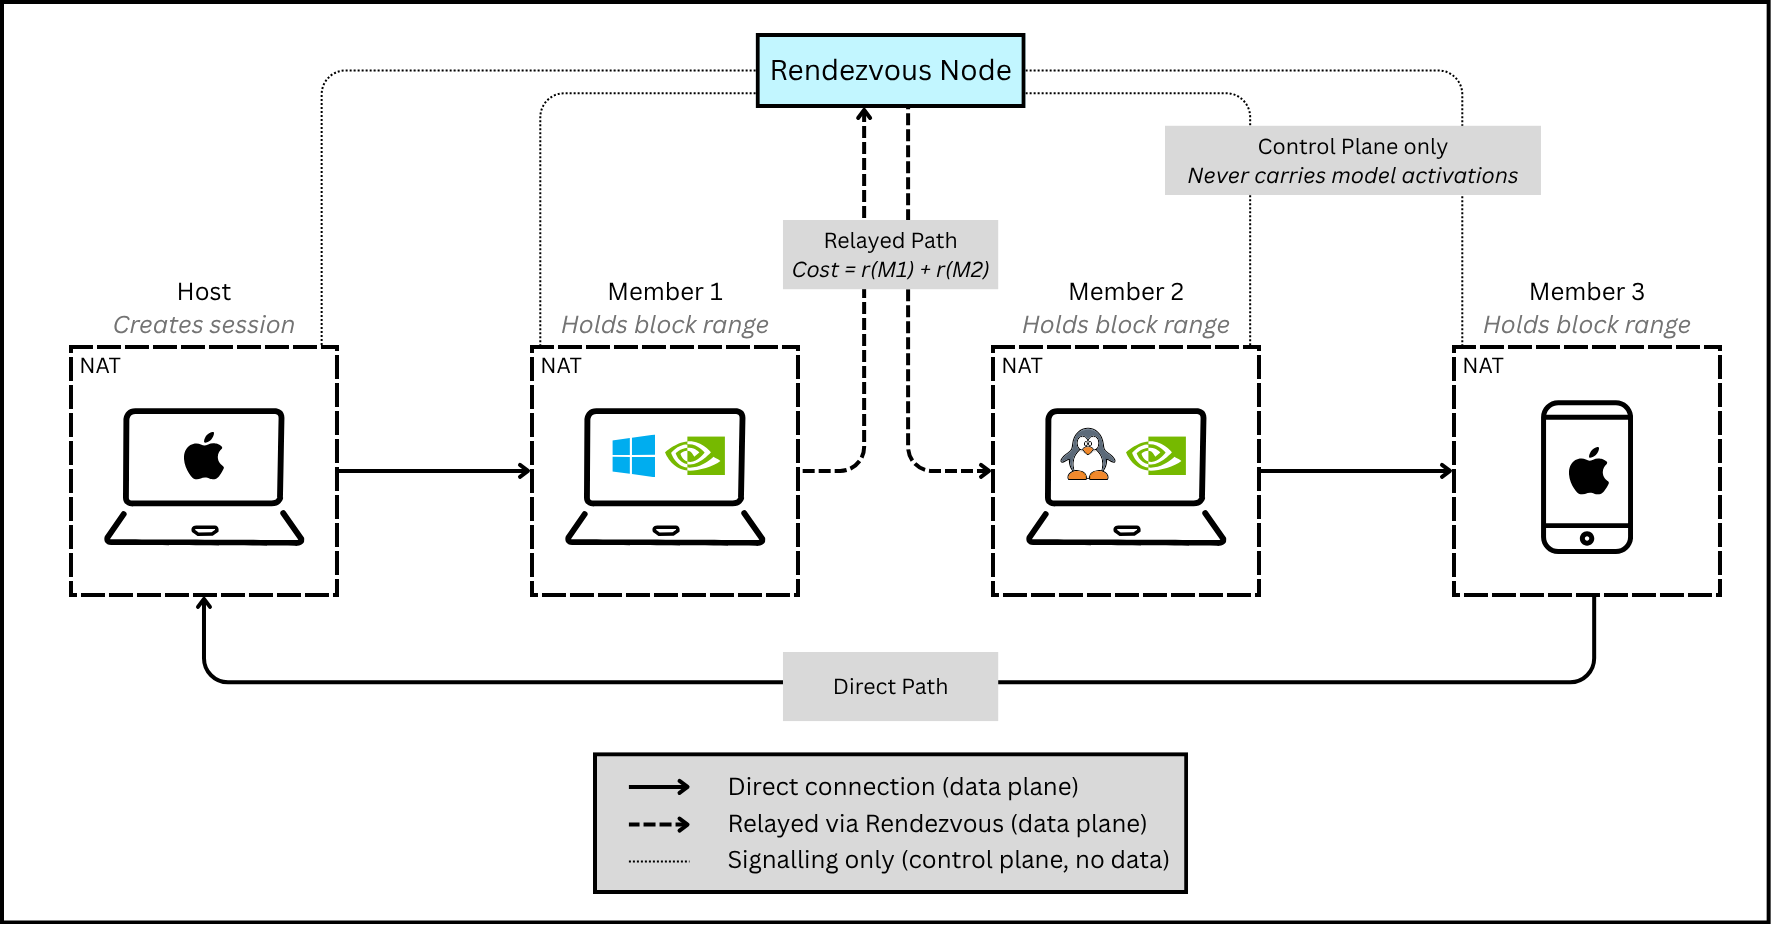
A ring assembled from behind independent NATs.
Members connect directly where they can. Where NAT traversal fails, that one link is relayed through the rendezvous node, which otherwise carries signalling only.
THE PLANNER
The division has to be right before serving begins.
A bounded session must use every device it admits, so its pipeline moves at the pace of the slowest stage. The planner measures each device's memory bandwidth, capacity and reachability, divides the model exactly for a fixed ring order, and places the head together with that division.
FIGURE 1: SESSION ARCHITECTURE
ABSTRACT
Between them, the members of a research group or a circle of friends own several consumer computers, none large enough alone to run a capable large language model. Existing systems pool such capacity across open swarms anyone may join, which a group admitting only trusted machines cannot use. Bounding membership removes what those systems depend on: a swarm holds each part of the model on several peers and routes around a slow one. A bounded session must use every device it admits. Its pipeline advances at the pace of whichever device received a share it cannot serve quickly, so the division has to be right before serving begins.
We propose Kafila. Its protocol assembles a ring from behind independent NATs, preferring direct paths and relaying where traversal fails, while its planner measures each device's memory bandwidth, capacity and reachability, divides the model exactly for a fixed ring order, and places the head, which holds the embedding and output projection, together with that division rather than beforehand.
On unequal machines in three countries Kafila shortens the slowest stage by 4.2× against uniform division and 2.6 to 3.5× against a memory-proportional one, and serves models for which uniform division admits no assignment at all. What that is worth to a user depends on how much of a token is computation rather than network. Across continents most of it is network; on members sharing a site the same division returns 1.6× the throughput to one user and 2.7× the aggregate to four.
- device-to-device coordination
- large language model inference
- heterogeneous devices
LISTEN
A narrated summary of the paper.